Engineering Metrics That Drive Improvement, Not Just Reporting
How mature engineering teams use meaningful measurement to improve delivery, remove bottlenecks and make better decisions. “What gets measured gets managed” is a familiar management principle. “What you don’t measure, you can’t manage” captures a related truth: without visibility, it is difficult to understand performance, identify problems or determine whether an improvement has worked. But measurement is not the same as management. And more measurement does not automatically lead to better outcomes. Engineering teams can generate extensive data from source control, delivery pipelines, issue trackers and production systems. They can track dozens of KPIs and produce detailed dashboards, yet still struggle to deliver predictably, maintain quality or understand why work gets delayed. The challenge is not simply to collect data. It is to determine what is worth measuring, what the evidence tells us, and what we should do differently as a result. For engineering leaders, tech leads and senior engineers, this is an important part of building an effective engineering organisation. 1. Start with established frameworks, not more KPIs There is no need to invent a new measurement framework for every engineering team. Established approaches provide useful starting points, each with a different emphasis. DORA: Software delivery performance DORA’s current framework uses five software delivery performance metrics to assess throughput and instability: Together, these measures help teams understand how effectively they deliver software and how reliably those changes perform. SPACE: A broader view of developer productivity The SPACE framework recognises that developer productivity cannot be understood through a single measure. It considers five dimensions: The frameworks complement each other. DORA provides a structured view of software delivery performance, while SPACE encourages a broader understanding of developer productivity, including the working environment and collaboration that influence outcomes. Neither framework is a universal scorecard, and adopting them does not mean measuring every dimension at once. For further reading, see DORA’s software delivery performance metrics and the SPACE framework research from Microsoft Research. 2. Start with the problem, not the dashboard Before introducing a metric, ask two questions: What problem are we trying to solve? What decision will this information help us make? Consider a team that consistently misses delivery commitments. Adding more KPIs will not necessarily explain why. The team first needs to understand where work is delayed and what is contributing to the problem. Depending on the situation, useful areas to investigate might include: These are investigation areas, not a mandatory KPI list. The relevant measures depend on the product, the team’s responsibilities and the decisions that need to be made. A practical approach is to: If the evidence already points to a likely cause, investigate it rather than adding another dashboard. 3. Avoid vanity metrics and analysis paralysis Every metric has a cost. Someone must collect or maintain the data, interpret it, discuss the findings and decide what to do next. When teams accumulate too many KPIs, they risk analysis paralysis: spending so much time reviewing information and debating interpretations that meaningful action is delayed. The volume of data can also obscure the few signals that deserve attention. Another risk is the use of vanity metrics: measures that appear to demonstrate productivity or progress but do not reliably establish meaningful outcomes. Consider some common engineering activity measures: These measures are not inherently useless. Their value depends on the question being asked and how the information is interpreted. They become misleading when used in isolation to rank engineers or draw conclusions the data cannot support. For example, comparing individual story points can encourage inflated estimates, discourage engineers from helping one another and undermine the planning process. An engineer handling a difficult architectural problem or mentoring colleagues may contribute substantially without closing many tickets. A more mature approach is to: The goal is not to measure everything. It is to measure enough to understand performance and make better decisions. 4. Automate measurement, not judgement Manual metric collection through spreadsheets, recurring status reports and presentations can create unnecessary work. It can also introduce inconsistencies, delays and reporting errors. Where practical, automate the collection, calculation and presentation of engineering metrics using data already available in the tools teams use. For example: Automation can make data more consistent and timely while reducing the administrative burden on engineers and managers. However, automation requires judgement of its own. DORA itself cautions against focusing on measurement at the expense of improvement. It can be more valuable to begin with existing data and team discussions than to invest heavily in integrations before understanding the problem. Automation should reduce reporting effort and improve decisions. It should not turn every aspect of engineering work into a surveillance mechanism. 5. Investigate bottlenecks, not just symptoms Consider a team that repeatedly misses delivery dates. A superficial assessment might conclude that engineers need to work faster. A more useful investigation follows the work through the delivery process. The team might discover that: Each finding suggests a different intervention: A targeted measure can establish a baseline and help determine whether the intervention is working. If code review delays are the suspected bottleneck, for example, the team could examine review waiting time and the age of outstanding reviews before and after changing its practices. The process is straightforward: A metric is most useful when it helps a team move from observing a problem to understanding and addressing its cause. 6. Improve team performance before blaming individuals When delivery performance deteriorates, some leaders turn to individual activity measures to determine who is underperforming. This can lead to the assumption that poor team results must be caused by individuals who are not working hard enough. Engineering performance is influenced by many factors, including: Looking at individual activity alone can cause leaders to overlook these constraints. The first objective should be to understand and improve the team’s delivery system, not to find someone to blame or remove. Blameless postmortems offer a useful principle. They focus on understanding what happened, the contributing conditions and the changes that could prevent recurrence, rather than beginning with blame. See Google’s SRE guidance
Developer Experience: Where Engineering Excellence Becomes Business Value
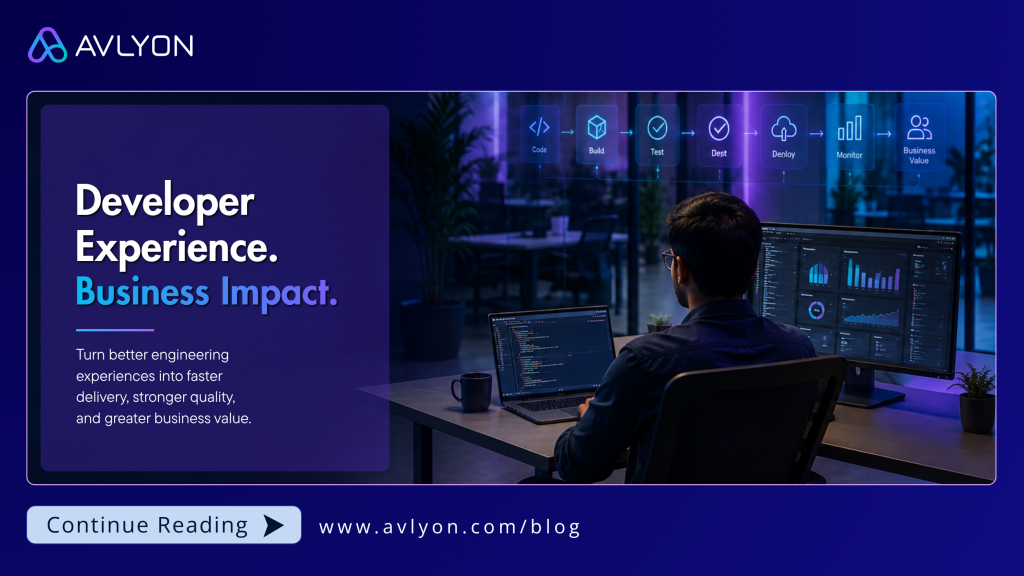
Developer Experience | Engineering Leadership Every company wants velocity. Few invest in the engine. Developer Experience, or DevX, is routinely treated as an internal engineering concern. Organizations talk about faster builds, better development environments, clearer documentation and automated pipelines as though they are simply conveniences for software engineers. The conversation often starts with a simple premise: engineers are more effective when their tools and processes get out of the way. That is true, but it misses the bigger picture. The real question is not simply whether developers experience less frustration. It is whether the way an organization builds software strengthens its ability to compete, execute and deliver value to customers. When viewed through this lens, DevX stops being a developer productivity initiative and becomes a business capability. A mature organization should not think about engineering in isolation. Investments in technology, engineering practices, platforms, AI capabilities and ways of working may begin inside the engineering organization, but their value should not stop there. They should improve delivery, strengthen business outcomes and ultimately create better experiences for clients, customers and end users. Developer Experience is a powerful example of this connection. Where most companies get stuck DevX has a persistent positioning problem. Leadership may hear the term and picture better code editors, expensive platform tooling or engineers optimizing pipelines for marginal efficiency gains. But organizations that deliver products quickly and adapt effectively to changing market conditions are not necessarily those with the largest teams or the biggest technology budgets. They are often the organizations with the least unnecessary friction between an idea and a reliable outcome. When engineering improvements start and end inside the technology team, they can struggle to secure sustained investment. However, when improvements to engineering systems contribute to faster time to market, better quality, more predictable delivery and stronger project economics, the conversation changes. DevX stops looking like an internal cost and becomes an investment in the organization’s ability to execute. This distinction is important because many organizations do not lack talented engineers or modern technologies. What they often lack is a deliberate approach to improving the system around those engineers. As teams and systems grow, small inefficiencies begin to compound, reducing the organization’s ability to turn engineering effort into delivered value. What scaling without DevX looks like The failure to address engineering friction rarely causes a sudden collapse. Instead, it creates a gradual and costly degradation of delivery capacity. A business identifies an urgent client or customer need. Product teams define the requirement, and engineers build the solution. Before that change reaches the customer, however, it may enter a maze of manual steps, fragile environments, slow test pipelines and fragmented documentation. Engineers spend time troubleshooting failed pipelines, requesting access, configuring environments and rediscovering knowledge that exists only in someone else’s head. Two organizations can employ equally talented engineers and adopt similar technologies. One may provide reproducible environments, reliable automated testing, accessible knowledge and clear system ownership, while the other depends heavily on manual handoffs, slow feedback and individual heroics. The headcount may be identical, but the effective engineering capacity is not. The difference lies in the engineering system around the people doing the work. Over time, this friction compounds. Release cycles become longer, small changes feel increasingly risky, and engineers spend more time navigating the delivery system than solving meaningful problems. By the time delayed roadmaps and missed opportunities become visible to leadership, the problem is often much larger than a missing tool. The delivery system itself has become increasingly difficult to change. The true economics of delivery friction Software creates value because it can change. Market priorities shift, security vulnerabilities emerge, regulations evolve, clients refine requirements and customers provide feedback. The ability to modify software safely and predictably is therefore one of the most important capabilities of a modern technology organization. Yet the true cost of a software change is rarely determined by the amount of code alone. It is influenced by the engineering effort required, the complexity of the system and the friction surrounding delivery. A useful way to think about it is: Cost of Change = Engineering Effort + System Complexity + Delivery Friction Some complexity is unavoidable, particularly in enterprise technology environments. However, a significant amount of delivery friction is created by the way organizations design their engineering systems, processes and ways of working. When unnecessary friction is reduced, the benefits can be seen across different delivery models. Protecting fixed-cost delivery economics In fixed-cost engagements, the commercial value of the project is agreed upfront. Every hour spent dealing with avoidable environment problems, manual processes or inefficient delivery workflows consumes engineering capacity. That capacity could otherwise be focused on solving client problems, improving quality or responding to changing needs. DevX helps protect delivery economics by reducing unnecessary internal friction and allowing more of the available engineering capacity to be directed towards meaningful outcomes. The benefit is not simply lower effort. It is a greater ability to convert engineering effort into client value. Compounding long-term product value For long-lived products, delivery friction compounds over time. When deployments are painful, teams tend to release less frequently. Larger and less frequent releases can introduce greater risk. When changes become difficult, improvements are postponed, and when feedback is slow, problems are discovered later. Over time, friction contributes to technical debt, and technical debt creates even more friction. A strong DevX foundation can help reverse this cycle. When changes are easier and safer to make, teams can improve systems continuously rather than waiting for large transformation programmes. The benefit compounds. An improvement to the engineering system today can make every future change easier. Transforming speed into quality Speed and quality are often presented as trade-offs. In a weak engineering system, they can be. Under delivery pressure, teams may reduce testing, postpone automation or take shortcuts that create problems later. That may appear faster in the short term, but the cost has simply moved elsewhere. A defect that could have been identified earlier becomes a production issue. A manual process